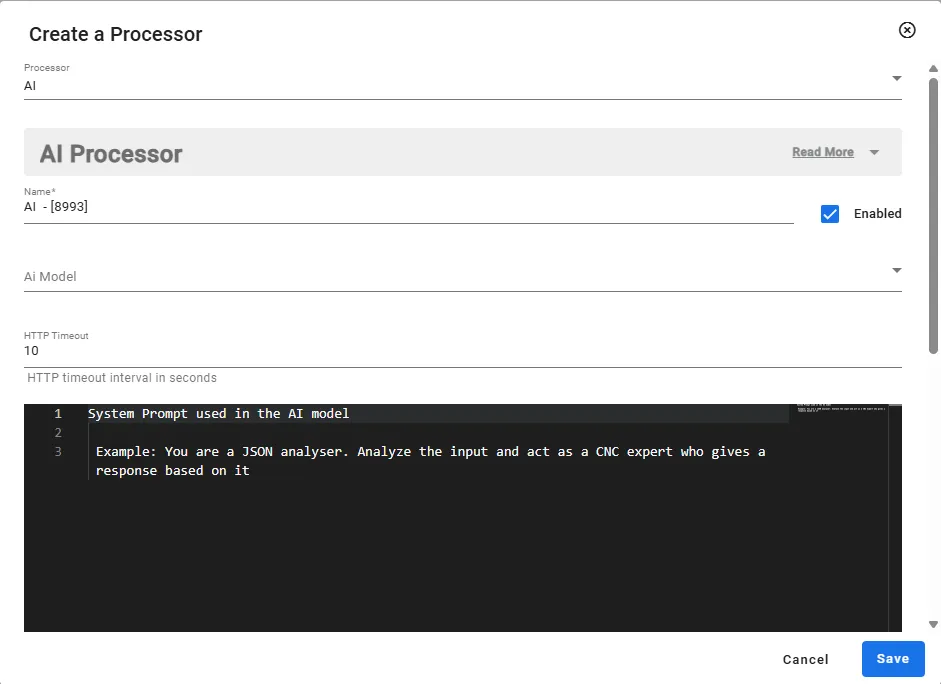
AI Processor
The AI Processor allows users to customize the behavior and output of the AI model through various parameters. These include defining a unique model name, setting system prompts to guide response tone and expertise, and adjusting temperature to influence response creativity.
The processor also allows users to limit the maximum length of generated responses with the completion tokens parameter and can enforce JSON formatting for structured outputs.
Additionally, it features an HTTP timeout setting to control the maximum wait time for AI responses, ensuring efficient operation and preventing delays.
AI Processor Overview
Set the following:
- AI Model defines the unique name identifier for the model being used.
- System Prompt parameter allows users to provide a predefined instruction that influences the AI’s behavior and response style.
- This can be used to enforce a specific tone, persona, or domain expertise in responses.
- Temperature parameter (default 1.0) controls the randomness of responses.
- Lower values (for example, 0.2) make the AI more focused and deterministic.
- Higher values (for example, 1.8) increase creativity but may reduce consistency.
- Max Completion Tokens parameter limits the maximum number of tokens the AI can generate in a single response.
- This ensures output length remains within expected boundaries.
- If not set, the model’s default value applies.
- Force Response Format to JSON? parameter determines whether the AI should strictly return responses in JSON format.
- If enabled, all responses will be structured as valid JSON Important: When using JSON mode, you must also instruct the model to produce JSON yourself through a system or user message
- If disabled, responses will follow the model's default output style
- HTTP Timeout parameter sets the maximum time (in seconds) the system waits for a response from the AI.
- If the AI does not respond within this time, the request timeouts and is ignored. This prevents excessive delays in cases of high latency.
AI Processor Parameters
Parameters | Details |
|---|---|
Name | The unique identifier assigned to differentiate each customized AI model. |
AI Model | Specifies the actual AI model used to generate responses. |
HTTP Timeout | Sets the maximum wait time (in seconds) for obtaining a response from the AI before it times out. |
File Path For Image | Indicates the location of an image file that can be accessed or processed by the AI. |
Code Editor | A tool or interface for writing and editing code, possibly for integration or customization involving the AI. |
Temperature | Controls the randomness of the AI’s responses, with lower values yielding more deterministic outputs and higher values fostering creativity. |
Max Completion Tokens | Limits the maximum number of tokens that the AI can generate in a single response. |
Time Interval | Defines a specific duration or frequency at which certain operations or requests should occur. |